
Text-Printed Image: Bridging the Image-Text Modality Gap for Text-centric Training of Large Vision-Language Models
Abstract
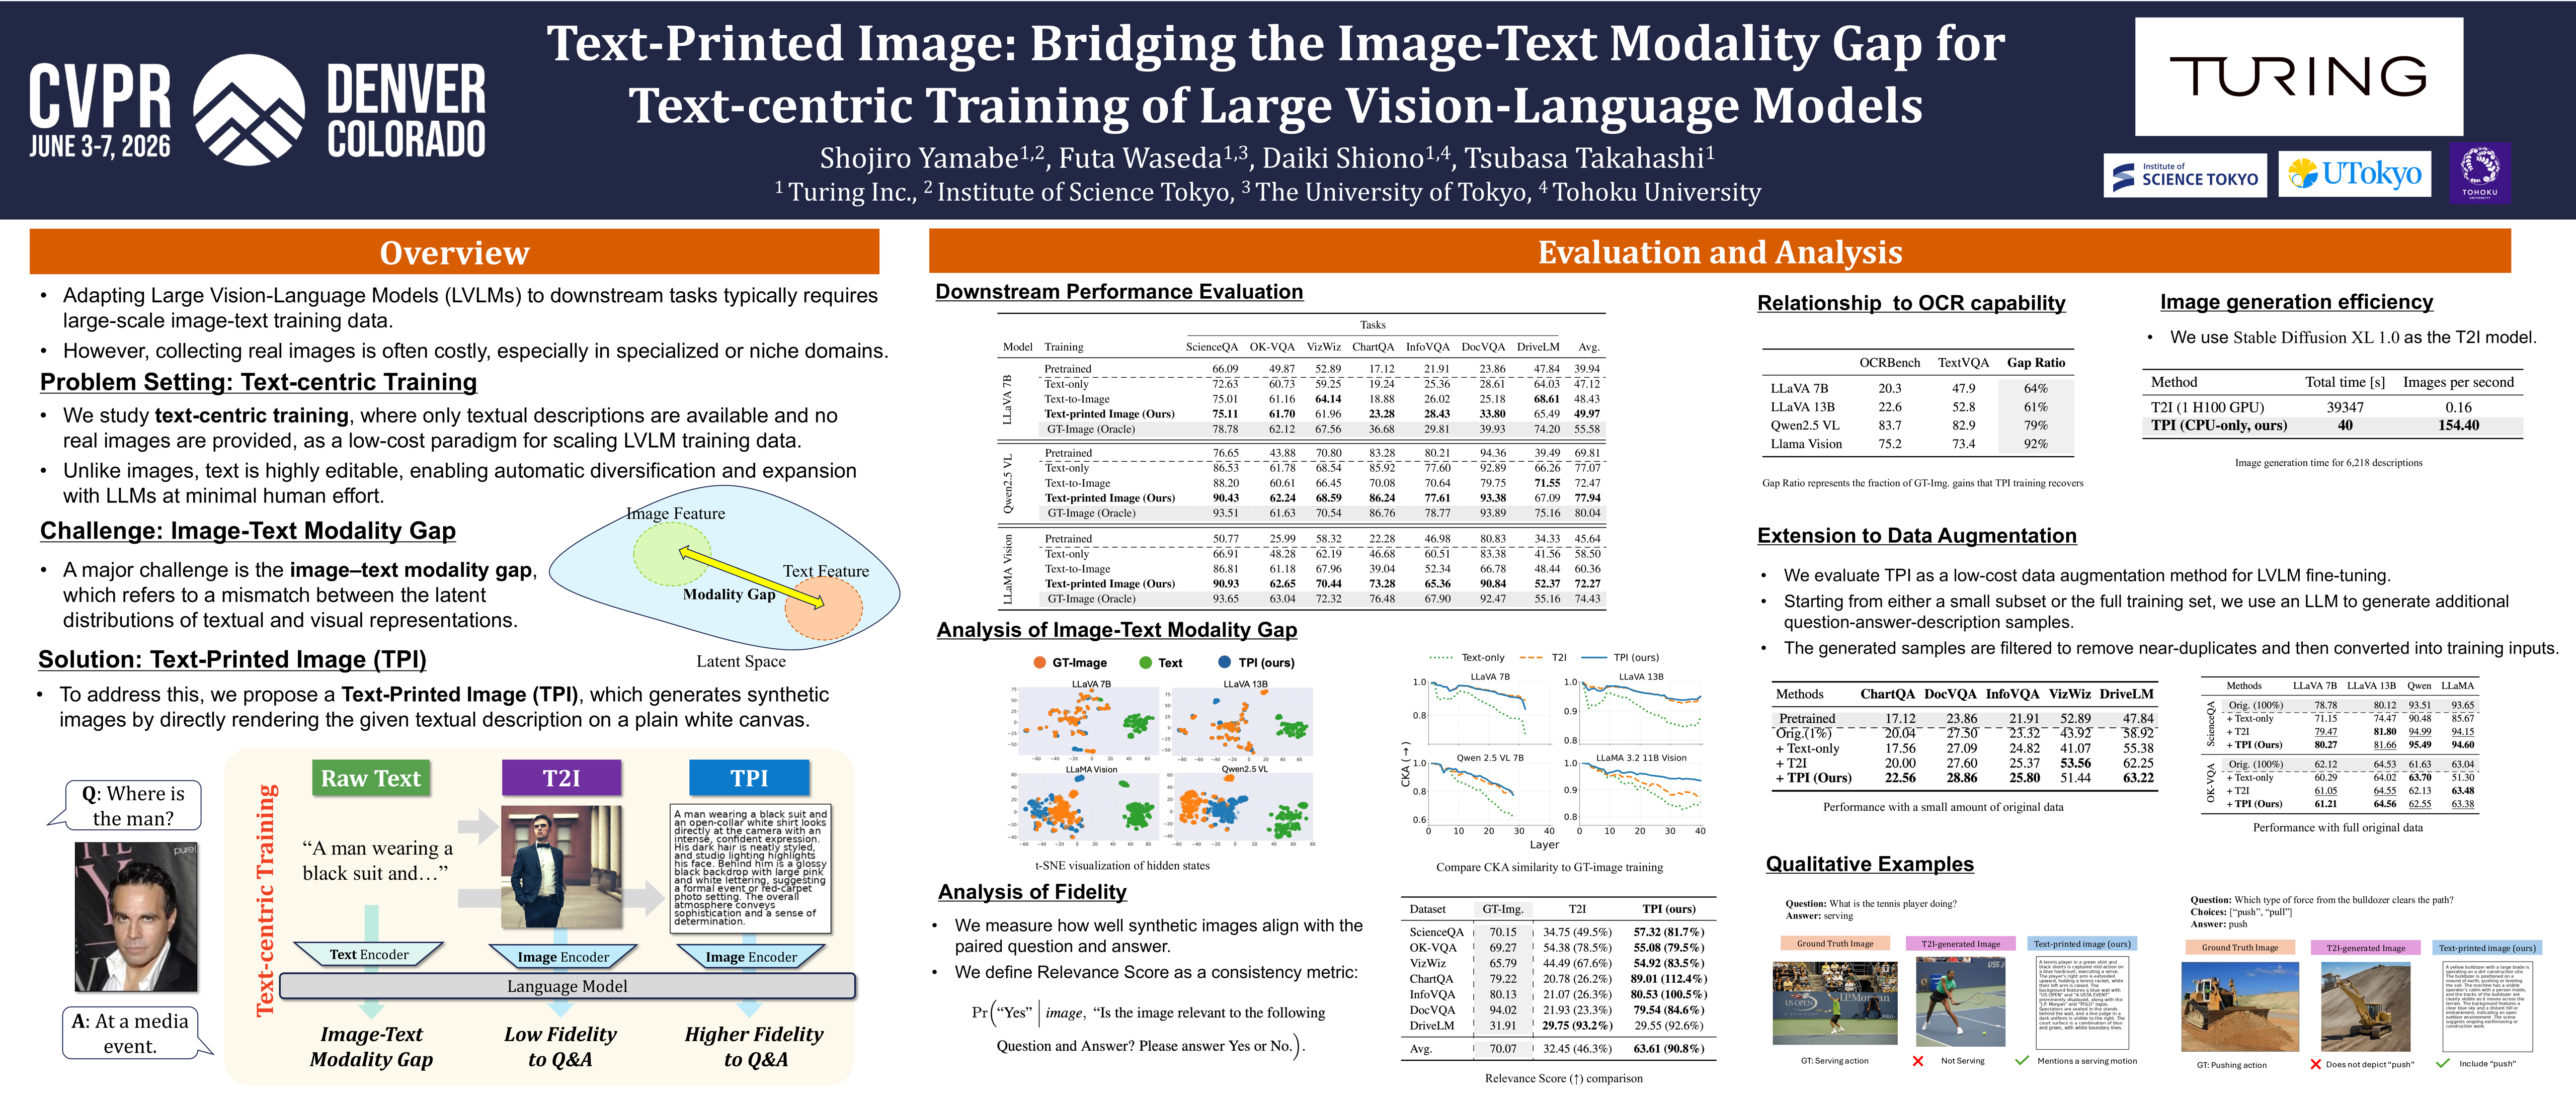
Recent large vision–language models (LVLMs) have been applied to diverse VQA tasks.However, achieving practical performance typically requires task-specific fine-tuning with large numbers of image-text pairs, which are costly to collect.In this work, we study text-centric training, a setting where only textual descriptions are available and no real images are provided, as a paradigm for low-cost data scaling.Unlike images, whose collection is often restricted by privacy constraints and scarcity in niche domains, text is widely available.Moreover, text is easily editable, enabling automatic diversification and expansion with LLMs at minimal human effort.While this offers clear advantages over image collection in terms of scalability and cost, training on raw text without images still yields limited gains on VQA tasks because of the image–text modality gap.To address this issue, we propose a Text-Printed Image (TPI), which generates synthetic images by directly rendering the given textual description on a plain white canvas.This simple rendering projects text into the image modality and can be integrated into arbitrary existing LVLM training pipelines at low cost.Moreover, TPI preserves the semantics of the text, whereas text-to-image models often fail to do.Across four models and seven benchmarks, our systematic experiments show that TPI enables more effective text-centric training than synthetic images generated by a diffusion model.We further explore TPI as a low-cost data-augmentation strategy and demonstrate its practical utility.Overall, our findings highlight the significant potential of text-centric training and, more broadly, chart a path toward fully automated data generation for LVLMs.